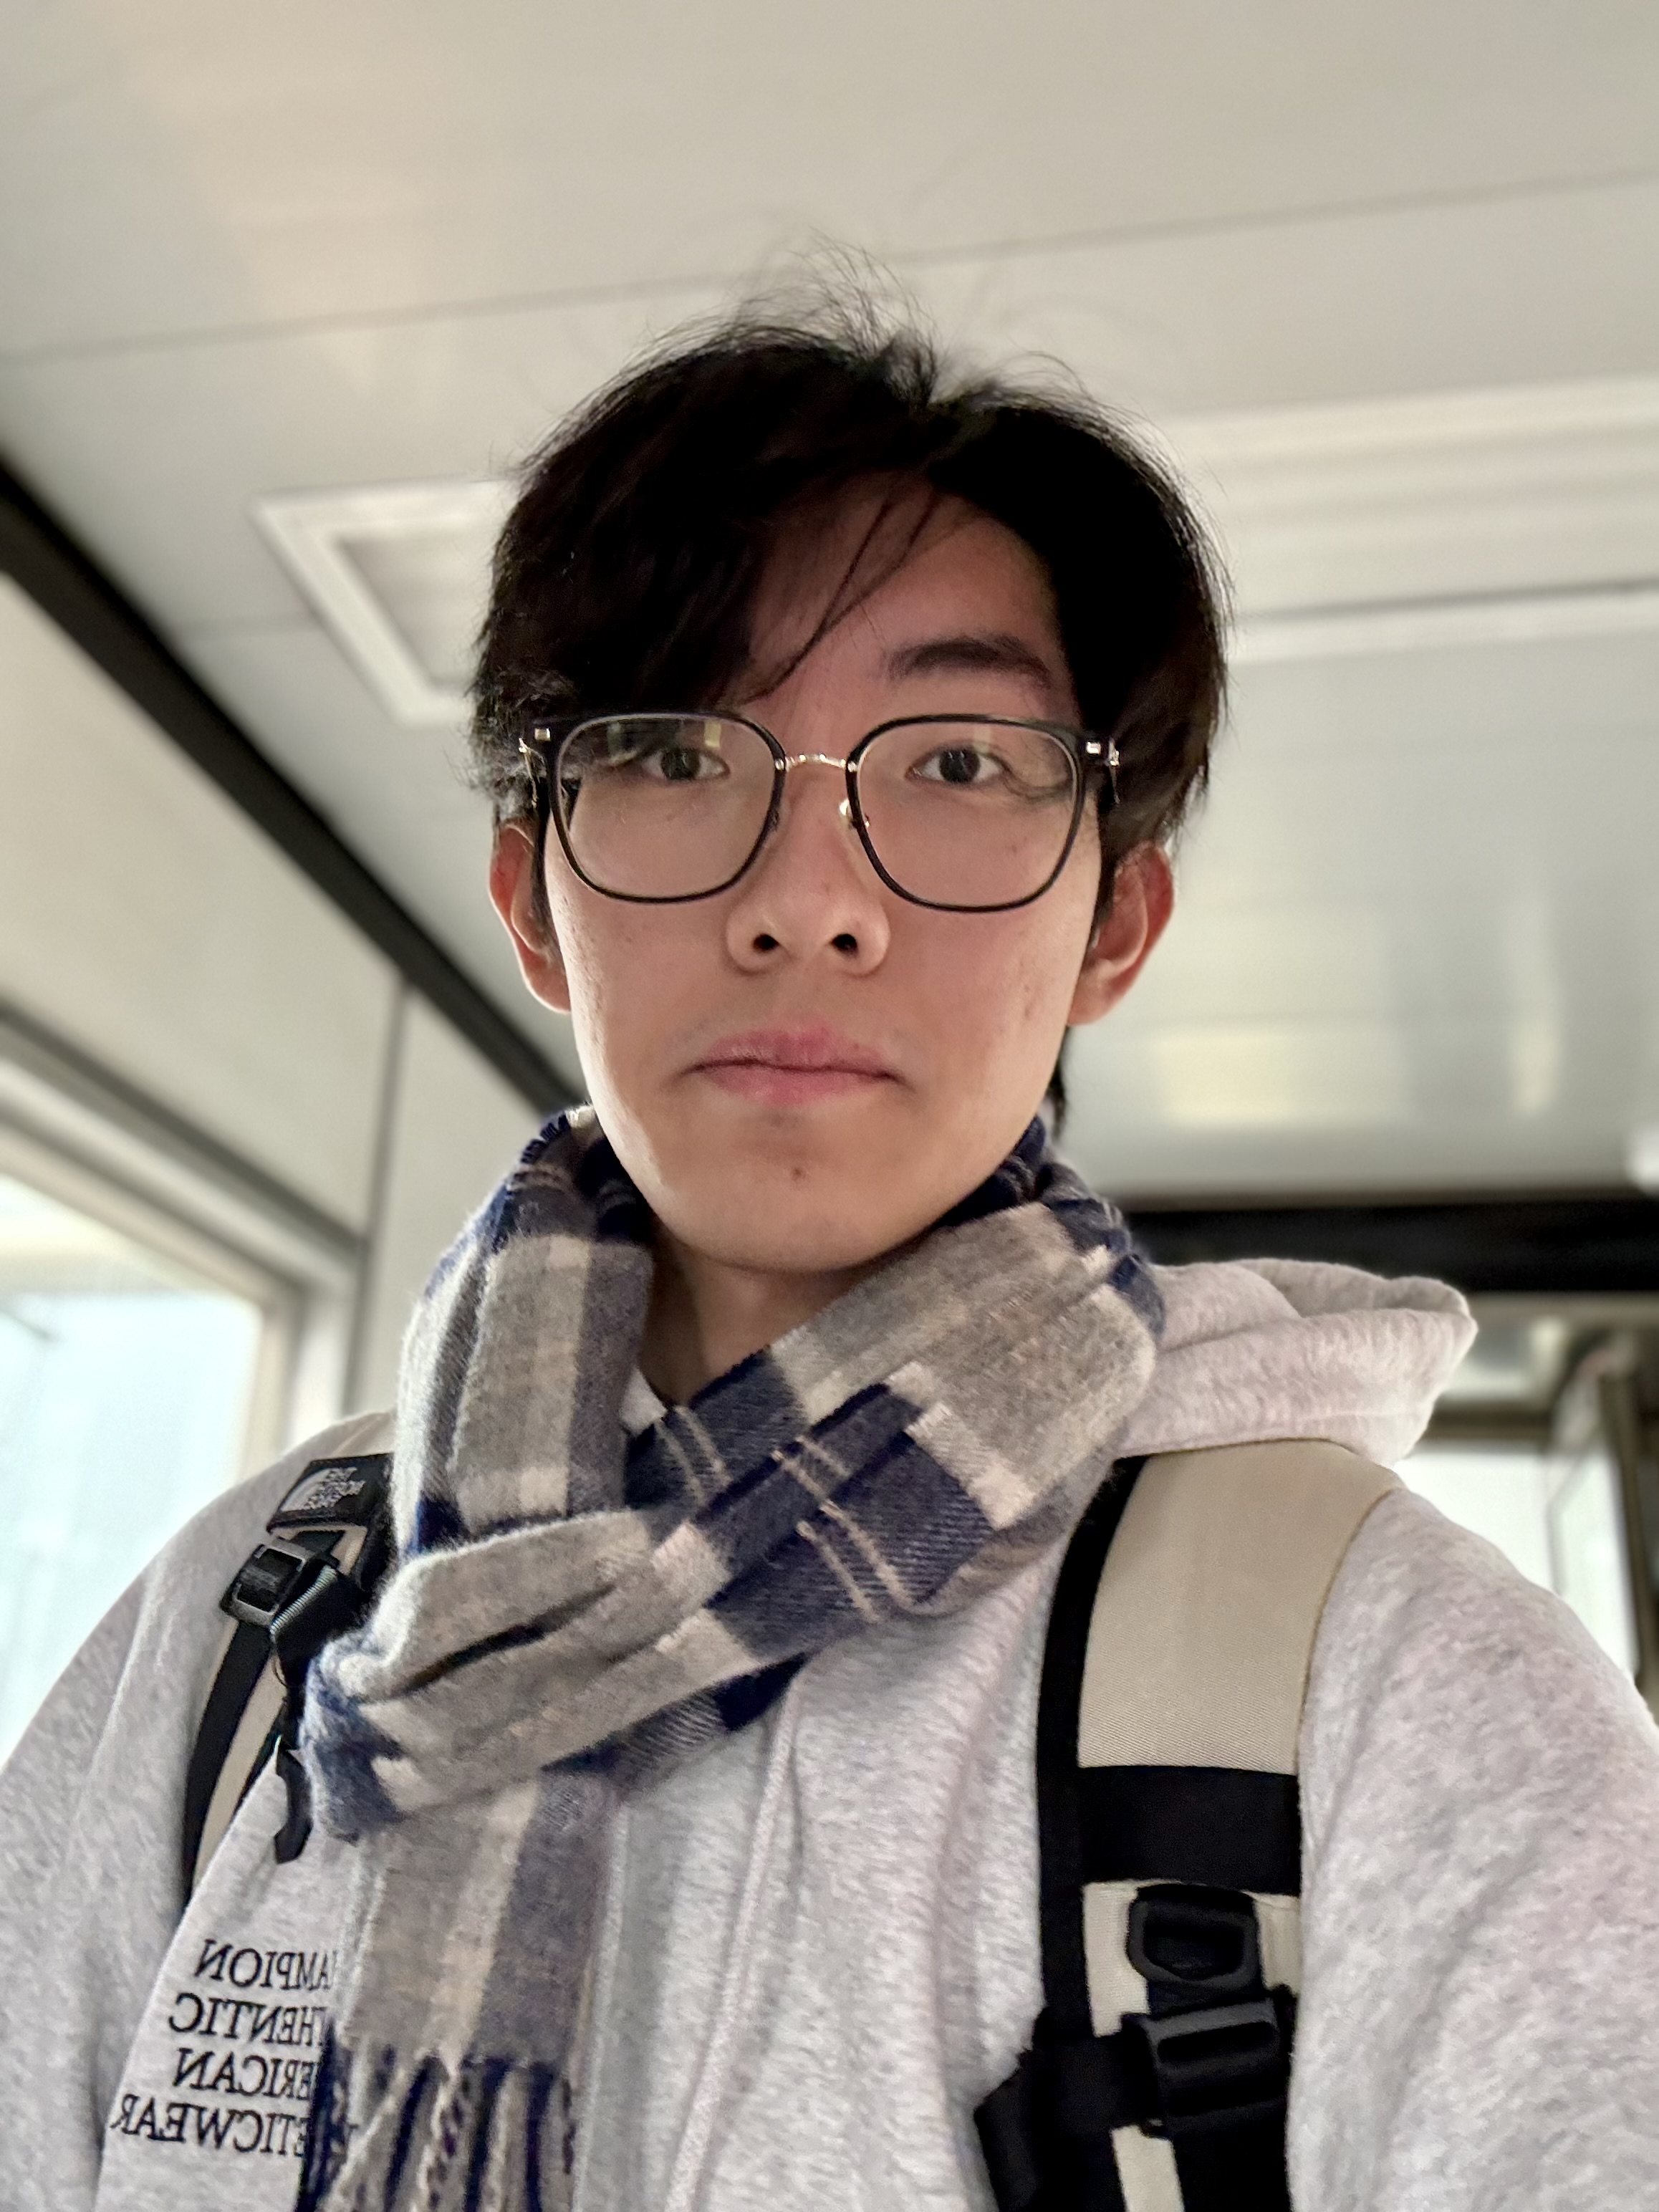
Chenyu Zhu (朱晨昱)
I am a final-year undergraduate student in Computer Science at City University of Hong Kong, graduating in June 2027. From June 2025 to June 2026, I worked as a Research Assistant in the Optima Research Group, Department of Computer Science, supervised by Prof. Zhichao Lu and Prof. Qingfu Zhang.
Feel free to reach out if you are interested in my work or have any ideas to discuss!
🔥 News
- 2026.09: My first-author paper Neural Spectral Capacity was accepted at NeurIPS 2026!
- 2026.09: Agents' Last Exam, to which I contributed, was accepted at NeurIPS 2026, Evaluations & Datasets Track.
- 2026.03: Our open-source project RL Explainer gained 129+ GitHub stars within 24 hours of launch!
- 2025.10: We release EvoEngineer, a framework for automated CUDA kernel code evolution with LLMs.
- 2025.06: Joined the Optima Research Group at CityU as a Research Assistant, working on evolutionary optimization and neural architecture search.
- 2024.06: Attended UC Berkeley Summer Session, studying CS 61BL and CS 188.
📝 Publications & Manuscripts
🔬 Research Experience
Learning and Optimization for Machine Intelligence (Optima) Research Group
June 2025 – June 2026Project 1: Neural Spectral Capacity (NSC)
- First-authored Neural Spectral Capacity (accepted at NeurIPS 2026), proposing a closed-form scalar that captures architectural structure (depth, head allocation, FFN ratio) from the network specification alone—no instantiation, no input data, no gradients—going beyond what parameters and FLOPs can see.
- Derived NSC by connecting each weight matrix's singular-value spectrum to the mutual information of a linear Gaussian channel, and used the Marchenko–Pastur law to reduce the expected per-matrix capacity to a deterministic expression in dimensions and initialization variance.
- Designed NSC-DP, an exact dynamic-programming solver that exploits NSC's layer-wise additivity to return the architecture globally maximizing NSC under resource constraints—a guarantee black-box search over existing training-free proxies cannot provide—running on a single CPU core over very large architectural search spaces.
- Led the empirical study across ranking, design, and compression: NSC outperforms parameters, FLOPs, and representative training-free proxies across multiple Transformer/CNN families; NSC-DP discovers a Transformer-XL variant on WikiText-103 that beats the human-designed baseline, and prunes LLaMA-7B without calibration data while matching or surpassing the strongest training-free baselines at a small fraction of the cost.
- Drove the full research pipeline end-to-end: theoretical formulation and proofs, algorithm design and implementation, experimental infrastructure, results analysis, figure preparation, and manuscript writing.
Project 2: Sand-NAS — Surrogate-Assisted Evolution for Native SNN Architectures
- Co-authored Sand-NAS (under review at IEEE TEVC), an LLM-based NAS framework that establishes a feasible paradigm for discovering native fully Spiking Neural Network (SNN) architectures for linear recurrent sequence modeling, addressing the joint mode-collapse and evaluation-cost bottlenecks of LLM-based NAS.
- Led the SNN analysis: characterized firing-rate dynamics, spike-driven accumulation behavior, and energy/efficiency properties of candidate architectures, providing the domain insights needed to assess whether LLM-generated candidates are genuinely "native" SNNs rather than ANN-to-SNN conversions.
- Designed the training-free surrogate model: extracted behavioral fingerprints from zero-cost proxies, code-level component statistics, structural shape-trace features, and SNN-specific firing-rate metrics, and trained a lightweight predictor that maps fingerprints to performance, surfacing promising candidates without expensive training.
- Built the surrogate-in-the-loop evaluation pipeline that progressively refines the predictor as the NAS process accumulates labeled architectures, sharply reducing the GPU-hour cost of evaluating candidates in this otherwise infeasible search.
- The discovered architectures achieve state-of-the-art performance with strictly linear computational complexity and extreme energy efficiency on long-context linear-recurrent benchmarks.
Project 3: EvoEngineer — Automated Code Evolution for GPU Kernels
- Co-authored EvoEngineer (accepted by IEEE Transactions on Big Data, 2026; arXiv:2510.03760), a framework that uses LLMs to automate the evolutionary optimization of CUDA kernels through iterative search in code space.
- Contributed to the code-evolution pipeline architecture, participating in the design of the iterative LLM-based search-and-refinement workflow for progressive CUDA kernel optimization.
- Built the end-to-end experimental infrastructure integrating KernelBench: automated compilation checks, correctness verification against reference PyTorch outputs, and GPU timing, enabling reproducible evaluation across a suite of real-world deep learning kernels.
- Contributed to manuscript writing and figure preparation.
🚀 Projects
RL Explainer | SvelteKit, TypeScript |
GitHub

Mar 2026
- Open-source project that gained 129+ GitHub stars within 24 hours of launch.
- Built an interactive web visualization of 11 reinforcement learning algorithms used in LLM post-training alignment, including GRPO, DAPO, GMPO, and GFPO.
📖 Education
City University of Hong Kong
Bachelor of Computer Science, Aug 2023 – Jun 2027 (Expected)
CGPA: 3.78 / 4.30
Core Curriculum: Data Structures (4.0/4.3), Discrete Mathematics (4.3/4.3), Design and Analysis of Algorithms (4.3/4.3), Computer Networks (4.0/4.3), Computer Organization (4.0/4.3), etc.
Awards: College of Engineering, Dean's List (2023/24 Sem A; 2024/25 Sem A, TGPA: 4.00; 2025/26 Sem A)
University of California, Berkeley
Summer Session, Jun 2024 – Aug 2024
GPA: 3.50 / 4.00
CS 188: Introduction to Artificial Intelligence (4.0/4.0); CS 61BL: Data Structures and Programming Methodology
🎖 Honors & Awards
- 2023 – 2026 College of Engineering, Dean's List (2023/24 Sem A; 2024/25 Sem A, TGPA 4.00; 2025/26 Sem A), City University of Hong Kong